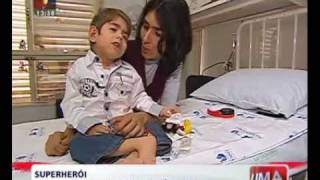
Miguel Canhoto "Super Herói" Reportagem TVI (Miguel - Síndrome de Pearson)
7,310 views (2012-03-02)Upload date: 2011-12-26⏱ 12:49👍 44 · 👎 2News & Politics
Status on YouTube
not checked
not checked yet
In the archive: 2012-01-30 – 2014-10-10.
Sources: Common Crawl 2012 · Web Archive – pages captured in 2013 · Web Archive – pages captured in 2014
Download the statistics: CSV · JSON
Sources: Common Crawl 2012 · Web Archive – pages captured in 2013 · Web Archive – pages captured in 2014
Download the statistics: CSV · JSON
Appeared on
Listed 9 times in captured pages, on 9 different lists (suggested videos, channels, playlists…). Earliest first:
- Channel page:
youtube.com/user/herfstdauw· capture of 2012-01-30 · nearest Wayback copy - Channel page:
youtube.com/user/RedAcid· capture of 2012-02-27 · nearest Wayback copy - Channel page:
youtube.com/user/sithgera· capture of 2012-02-27 · nearest Wayback copy - Comments page:
youtube.com/all_comments?v=DocMc6puhPw· capture of 2012-03-02 · nearest Wayback copy - Channel page:
youtube.com/user/PsicoVpa· capture of 2012-03-10 · nearest Wayback copy - Suggested next to: 2012 04 23 Coragem na escola Repórter TVI.avi · capture of 2013-03-13 · this capture in the Wayback Machine
- Channel page:
youtube.com:80/user/andrepcg/videos· capture of 2013-09-13 · nearest Wayback copy - Suggested next to: 2011 02 04 Segurança na internet SIC.avi · capture of 2014-05-11 · this capture in the Wayback Machine
- Suggested next to: Leonor Mel Ahrens Teixeira - uma história tocante · capture of 2014-06-09 · this capture in the Wayback Machine
Description
Reportagem da TVI "Super Herói"
Miguel Canhoto é um rapaz de 6 anos que possui a Síndrome de Pearson.
A Síndrome de Pearson é uma citopatia mitocondrial, rara, que envolve o sistema hematopoiético, habitualmente fatal na infância.
(O video possui alguns problemas que tentei corrigir ao máximo, não houve maneira de o colocar a 100%, portanto existem alguns atrasos e interrupções)
Miguel Canhoto é um rapaz de 6 anos que possui a Síndrome de Pearson.
A Síndrome de Pearson é uma citopatia mitocondrial, rara, que envolve o sistema hematopoiético, habitualmente fatal na infância.
(O video possui alguns problemas que tentei corrigir ao máximo, não houve maneira de o colocar a 100%, portanto existem alguns atrasos e interrupções)
Tags
Other titles
- Miguel Canhoto "Super Herói" Reportagem TVI (Mi...
View history
watch pagelist (suggested, channel, search…)
Captures with a view count: 9 (the watch page and the lists that showed the video).
Archive captures (1)
| Captured | Source | Captured URL | Original | Status | Views | Likes / dislikes |
|---|---|---|---|---|---|---|
| 2012-03-02 | CC 2012 | youtube.com/watch?v=DocMc6puhPw | available | 7,310 | 44 / 2 |
The captured URL is the exact address of the page when it was captured, country host and parameters included. For Common Crawl it opens the record in that crawl's index (WARC file and offset), and the HTML button downloads the page's original code from Common Crawl. For the Web Archive it opens that very capture in the Wayback Machine. The date of a Common Crawl capture opens the nearest Wayback copy of the page.